
Genuine PDF Corpus (PDF-Forensics)
Original PDFs for document-forensics research.
v1.3.1 · · Scam AI
- PDFs
- 82,955
- Uncompressed
- 51.0 GB
- PDF parts
- 6
The original pages
Two legislation PDFs, selected and checked by an AI agent. Illustrative, not a representative sample. Personal financial and court records are not previewed.
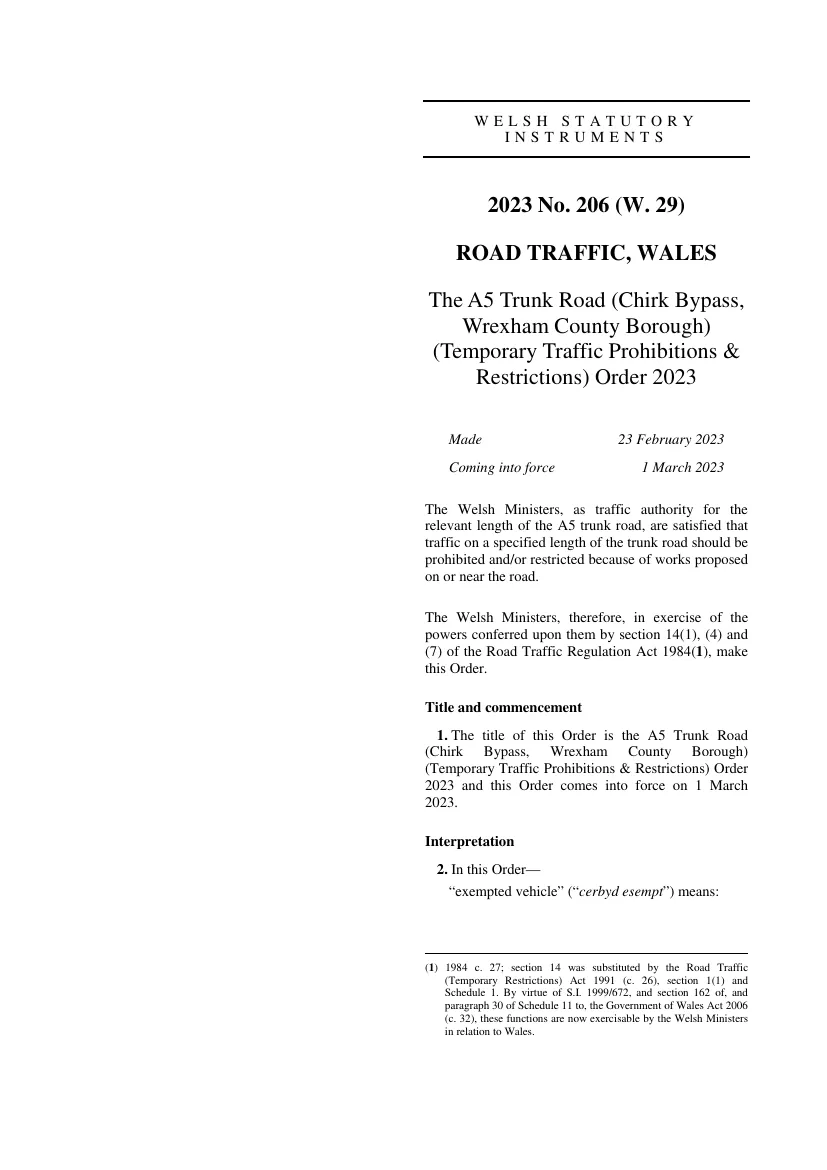
UK statutory instrument
The blank left half is part of the source PDF.
Contains public sector information licensed under the Open Government Licence v3.0 (Crown © and database right, legislation.gov.uk). Open Government Licence v3.0.
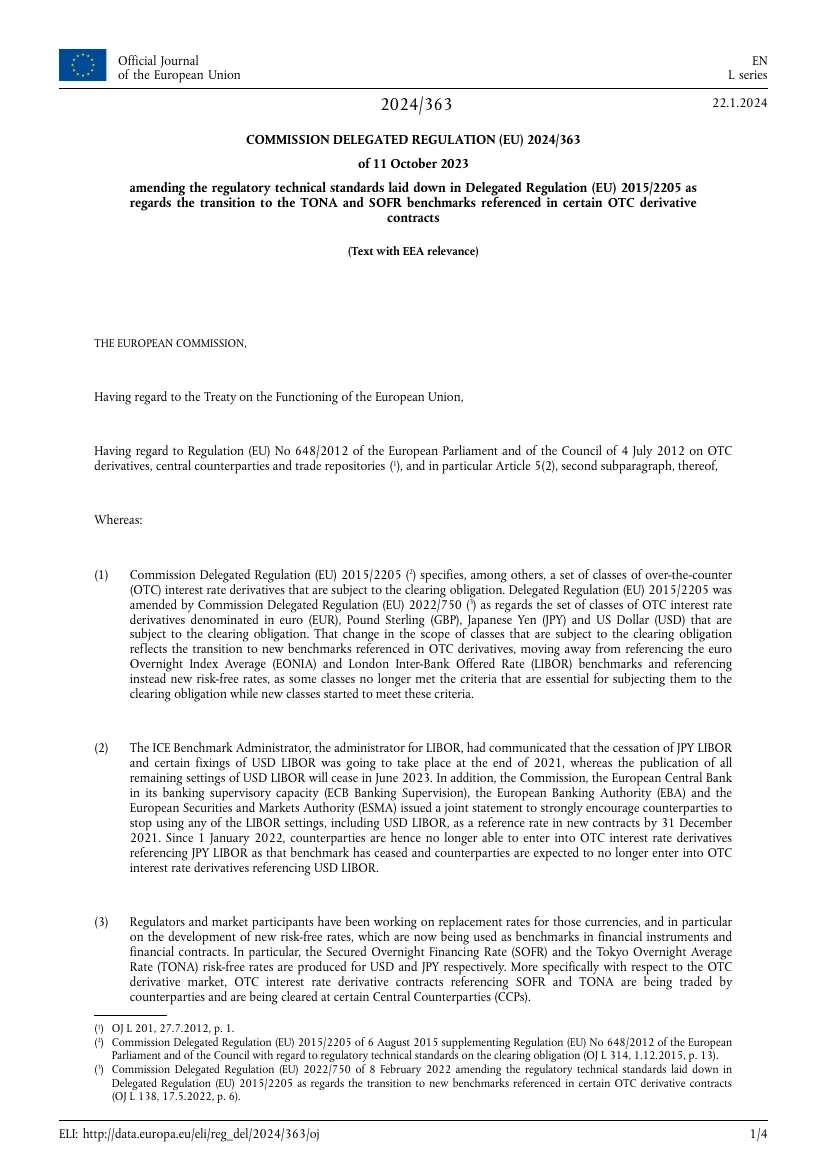
EU delegated regulation
© European Union, https://eur-lex.europa.eu, 1998–2026. Commission Decision 2011/833/EU.
What is in the corpus
56 source groups across 14 jurisdictions. Document-type, format and language labels are machine-assigned or supplied by the source. No edited or synthetic documents.
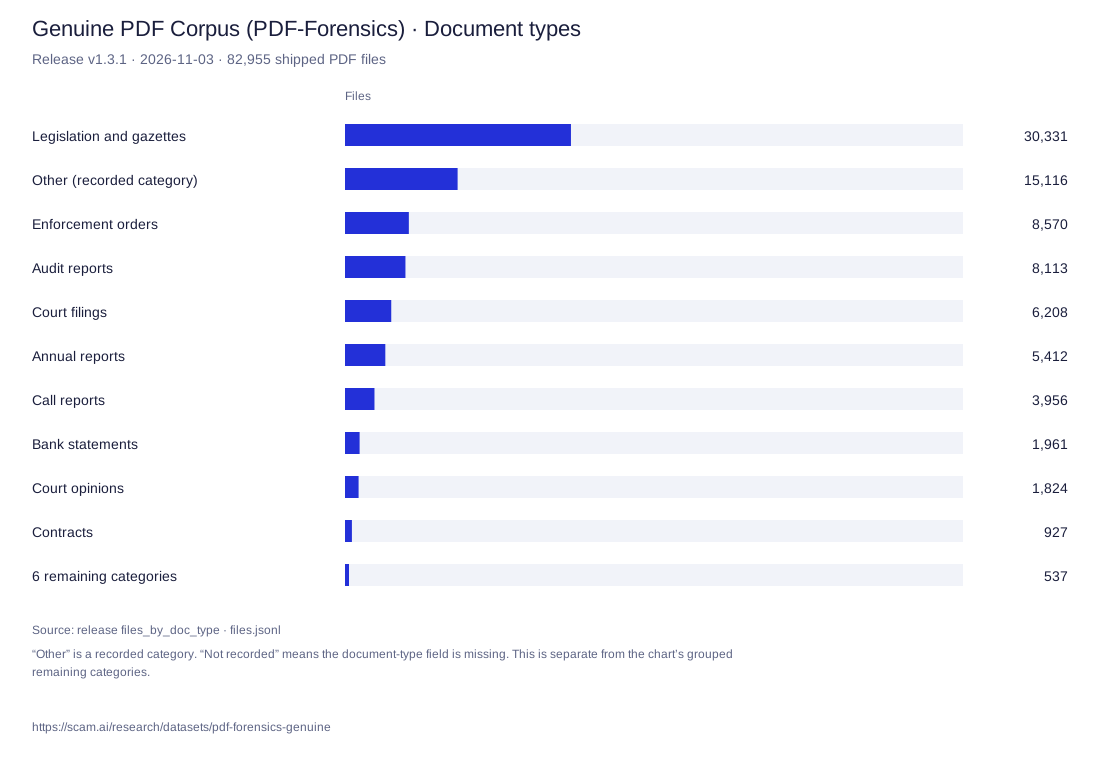
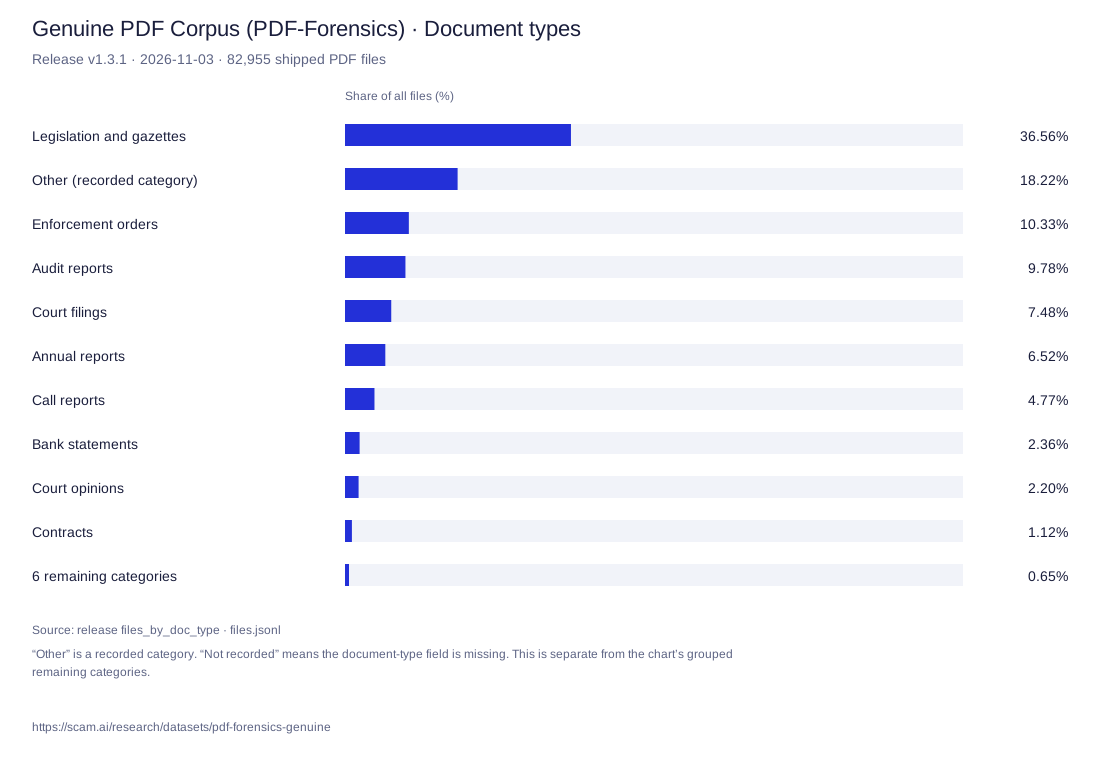
Document types
82,955 shipped files
“Other” is a recorded category. “Not recorded” means the document-type field is missing. This is separate from the chart’s grouped remaining categories.
All 16 categories
| Category | Files | Share |
|---|---|---|
| Legislation and gazettes | 30,331 | 36.56% |
| Other (recorded category) | 15,116 | 18.22% |
| Enforcement orders | 8,570 | 10.33% |
| Audit reports | 8,113 | 9.78% |
| Court filings | 6,208 | 7.48% |
| Annual reports | 5,412 | 6.52% |
| Call reports | 3,956 | 4.77% |
| Bank statements | 1,961 | 2.36% |
| Court opinions | 1,824 | 2.20% |
| Contracts | 927 | 1.12% |
| Invoices | 287 | 0.35% |
| Loan disclosures | 208 | 0.25% |
| Not recorded | 34 | 0.04% |
| Pay stubs | 4 | <0.01% |
| Other tax forms | 3 | <0.01% |
| Utility bills | 1 | <0.01% |
| Total | 82,955 | 100.00% |
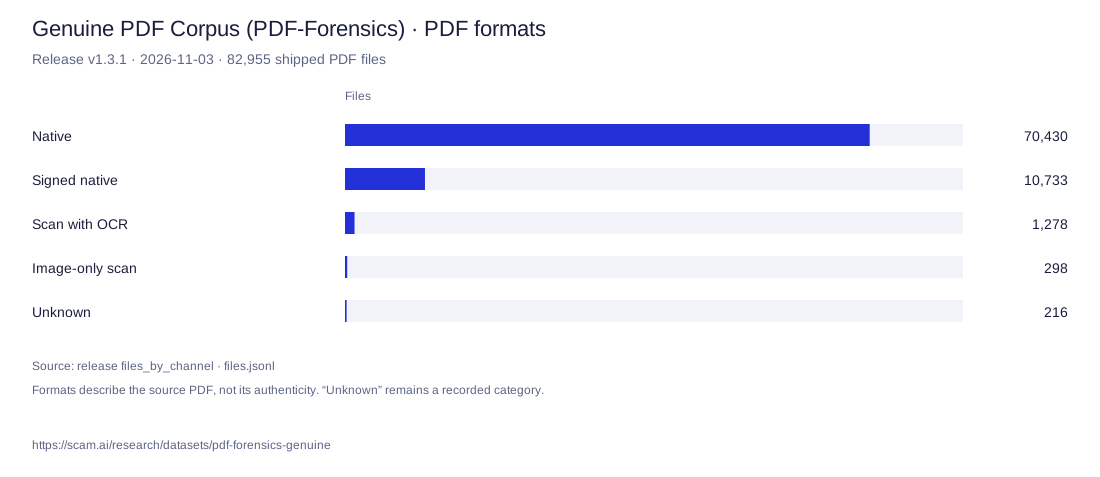
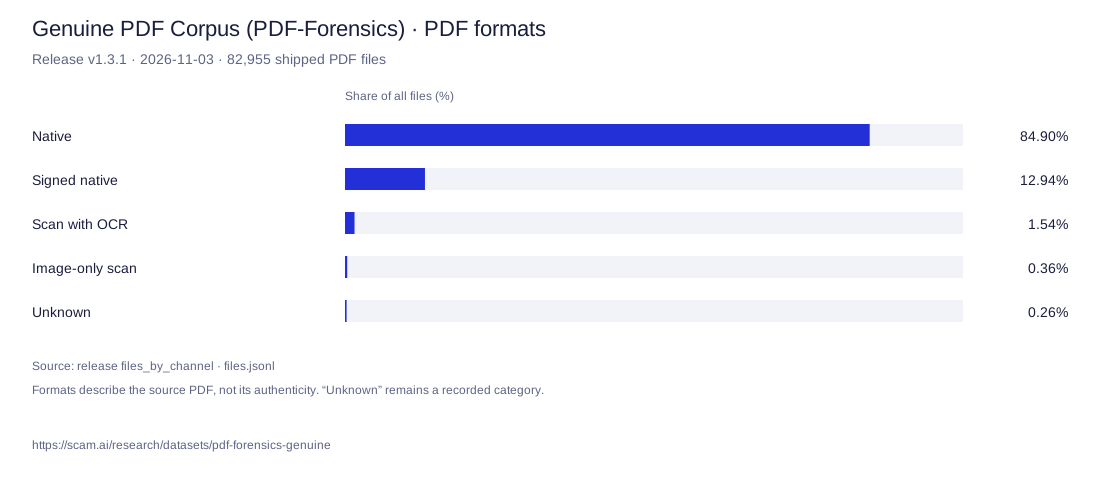
PDF formats
82,955 shipped files
Formats describe the source PDF, not its authenticity. “Unknown” remains a recorded category.
All 5 categories
| Category | Files | Share |
|---|---|---|
| Native | 70,430 | 84.90% |
| Signed native | 10,733 | 12.94% |
| Scan with OCR | 1,278 | 1.54% |
| Image-only scan | 298 | 0.36% |
| Unknown | 216 | 0.26% |
| Total | 82,955 | 100.00% |
Languages
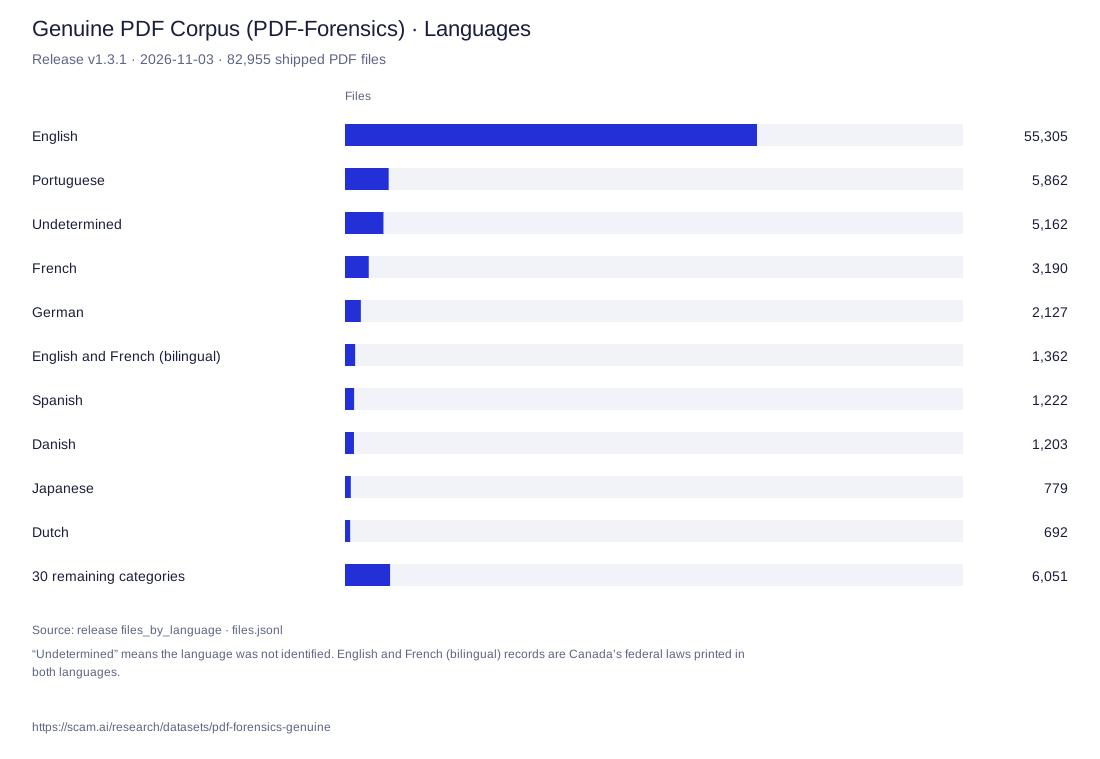
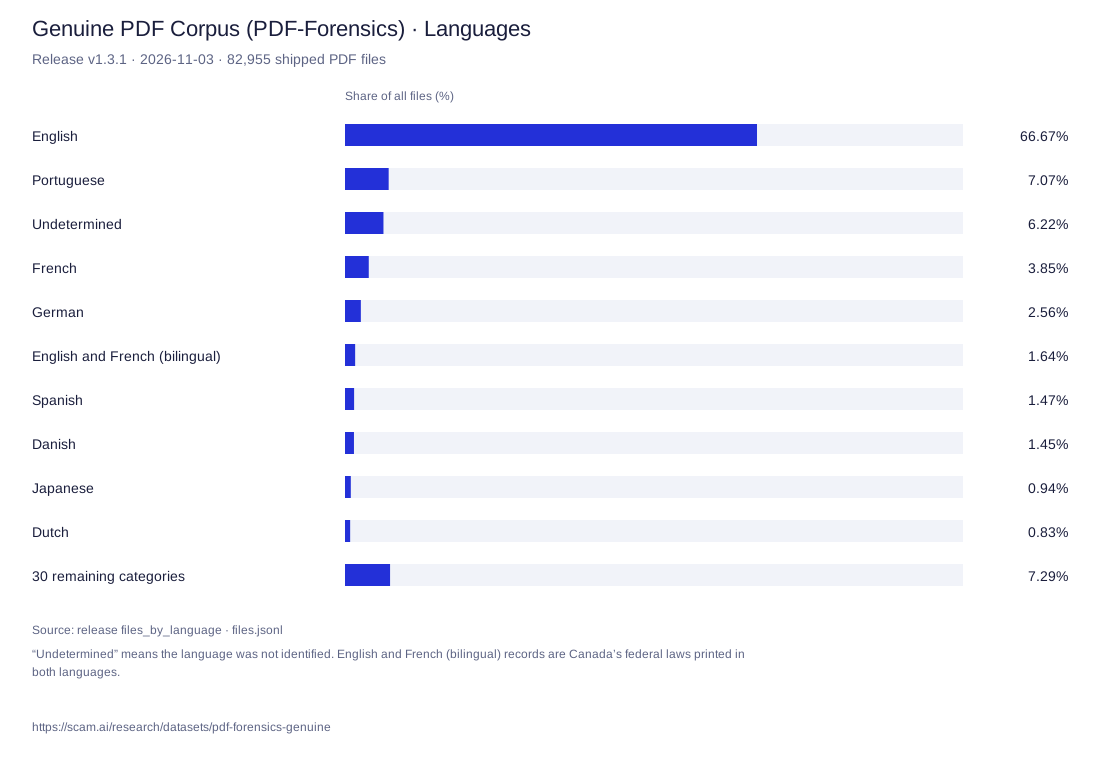
82,955 shipped files
“Undetermined” means the language was not identified. English and French (bilingual) records are Canada’s federal laws printed in both languages.
All 40 categories
| Category | Files | Share |
|---|---|---|
| English | 55,305 | 66.67% |
| Portuguese | 5,862 | 7.07% |
| Undetermined | 5,162 | 6.22% |
| French | 3,190 | 3.85% |
| German | 2,127 | 2.56% |
| English and French (bilingual) | 1,362 | 1.64% |
| Spanish | 1,222 | 1.47% |
| Danish | 1,203 | 1.45% |
| Japanese | 779 | 0.94% |
| Dutch | 692 | 0.83% |
| Latvian | 416 | 0.50% |
| Slovenian | 416 | 0.50% |
| Estonian | 415 | 0.50% |
| Finnish | 415 | 0.50% |
| Maltese | 415 | 0.50% |
| Lithuanian | 413 | 0.50% |
| Greek | 412 | 0.50% |
| Croatian | 410 | 0.49% |
| Irish | 409 | 0.49% |
| Bulgarian | 404 | 0.49% |
| Slovak | 404 | 0.49% |
| Polish | 238 | 0.29% |
| Italian | 237 | 0.29% |
| Czech | 232 | 0.28% |
| Swedish | 231 | 0.28% |
| Romanian | 230 | 0.28% |
| Hungarian | 229 | 0.28% |
| Chinese | 44 | 0.05% |
| Norwegian | 36 | 0.04% |
| Swahili | 27 | 0.03% |
| Lao | 4 | <0.01% |
| Armenian | 3 | <0.01% |
| Amharic | 2 | <0.01% |
| Arabic | 2 | <0.01% |
| Haitian Creole | 2 | <0.01% |
| Azerbaijani | 1 | <0.01% |
| Indonesian | 1 | <0.01% |
| Korean | 1 | <0.01% |
| Tagalog | 1 | <0.01% |
| Vietnamese | 1 | <0.01% |
| Total | 82,955 | 100.00% |
A screened collection of originals
Study coverage, compare other detectors and follow each file back to its source. Keep the selection process in view.
Selection and provenance
Source files were deduplicated by SHA-256, checked against source-licence and privacy rules, and kept as original PDF bytes. Employee and customer-provided files are excluded.
Of 95,245 candidate originals, 82,955 were retained after Trustable engine 0.18.0 read them CLEAN in scans on 31 October and 1 November 2026. The other 12,290 were withheld: flagged or inconclusive files, unfinished scans, and internal evaluation holdouts.
Each record provides its SHA-256, byte count, package path, provenance, source URL where recorded, document labels and licence information. There is no edited-pair or edit-operation catalogue.
Evaluation limits
The release includes 81,163 born-digital PDFs, including 10,733 with digital signatures, 1,576 scans and 216 with unknown format. Source and format imbalance can affect alert rates.
The CLEAN selection favours files that engine finds unambiguous. It cannot measure that engine’s false-positive rate. There are no edited positive examples, so it cannot alone measure forgery-detection recall, overall accuracy or performance on benign editing.
Labels have no independent human validation. “Genuine” means a collected original with no recorded edit; it does not certify the issuer or contents. A CLEAN reading is not proof of authenticity.
Report input counts, completed checks, unsupported inputs and failures separately. Review alerts and establish independent ground truth before calling an alert rate a false-positive rate.
Download and verify
In Marketplace, open Genuine PDF Corpus (PDF-Forensics), press Download and choose the parts you need. Read the metadata before downloading the PDF archives.
6 PDF archives + metadata
The six independent part-NNNNN.tar.zst archives are storage groups, not train/test splits. Do not concatenate them. They expand under files/.
| File | Contents |
|---|---|
archives.json | Part names, compressed sizes, PDF counts and SHA-256 values. |
ARCHIVE_ | Checksums for all six PDF parts and the metadata archive. |
metadata.tar.zst | files.jsonl, its CSV mirror, the data card, download guide, summary, changelog, citation, licences, attribution and per-part manifests. |
Start with DATASET_CARD.md, DOWNLOADS.md, LICENSES.md, ATTRIBUTION.md, summary.json and licences/. For partial downloads, verify only the matching checksum lines.
Verify archives and extract a part
# GNU tar, sha256sum and zstd; run beside the downloads.
# This checks every archive listed; missing files fail verification.
sha256sum -c ARCHIVE_SHA256SUMS

mkdir dataset
tar --zstd --extract --file metadata.tar.zst --directory dataset --no-same-owner
tar --zstd --extract --file part-00000.tar.zst --directory dataset --no-same-owner
Check the extracted bytes
cd dataset
sha256sum -c SHA256SUMS

# Python 3: verify the PDF bytes in one extracted part.
python3 -c 'import json, sys
for line in open(sys.argv[1]):
    r = json.loads(line)
    print(r["sha256"] + "  " + r["path"])' parts/part-00000.jsonl |
  sha256sum -c --quiet
Source licences, privacy and takedown
Licences stay with each file
The release has 33 licence records: 49,246 files under redistribution-permitting licences, 26,914 requiring attribution and 6,795 public court records with no licence statement found, shipped under the publisher’s public-record rule. There is no blanket licence.
Check each file’s record, LICENSES.md, ATTRIBUTION.md and licences/. Preserve notices and required credit; public availability does not grant every use.
Public does not mean de-identified
The existing screen checks for Social Security numbers and full account numbers. It does not remove names or home addresses. Do not target or profile people named in public records or misrepresent a research copy as an issuer’s authenticated document.
For rights or privacy concerns, contact the dataset support team with the file’s SHA-256 or release path.
BibTeX
@misc{scamai-pdf-forensics-genuine,
  author = {{Scam AI}},
  title = {{Genuine PDF Corpus (PDF-Forensics)}},
  year = {2026},
  version = {1.3.1},
  howpublished = {\url{https://scam.ai/research/datasets/pdf-forensics-genuine}},
  note = {Dataset, version 1.3.1, dated 2026-11-03}
}